

Reading video and documents
Two AI nodes read what pictures alone cannot carry. Video Analysis watches a video — images and sound together —
and answers a question about it. Document Analysis reads one or more documents — PDFs, plain text, Markdown — and
does the same. Both work like Text Generation: a prompt with the question, an optional
system_prompt with the role and the rules, Max Tokens, a choice of models, and Response Format JSON Object when
the answer must become data.
Video Analysis (ai/video_analysis) |
Document Analysis (ai/document_analysis) |
|
|---|---|---|
| Reads | one video |
1 to 20 documents: PDF, .txt, .md |
| Models | Gemini only; Gemini 3.8 Flash by default | GPT and Claude; GPT-6 Luna by default |
| Good for | a summary, chapters, a description of a clip, what is said and shown, a check before publishing | the lines and totals of a quote, the dates and parties of a contract, the items of a price list, a summary |
| Typical cost | about 0.31 credits per minute of video (Gemini 3.8 Flash) | under 0.1 credits per page with Luna (0.046 for the one-page quote of the lab) |
Video Analysis
Section titled “Video Analysis”The node sends the whole video to a Gemini model, which sees about one frame per second and hears the sound. Ask what you would ask a colleague who watched it: summarise it in three sentences, list the chapters with the time each one begins, what product is shown and in which colours, is there any text on screen, how many people speak.
- Times are approximate. In the lab the chapters came within three seconds of the phrase they name, most of them on the second; with Gemini 2.5 Flash they came 2 to 8 seconds early, once 18. That is good for an index or a summary, not for cutting. For exact times use Speech to Text, whose captions carry the time of every phrase, and Highlights for moments chosen to be cut.
- Exact scene edges, and models that do not read video. Extract Scenes measures
where every scene starts and ends, at no credit cost, and takes a frame of each labelled with its time; with the
frames on Image Analysis’s
image_setand the transcript in the prompt, a model that sees images but not video (GPT-6 Luna, Claude Sonnet 5.5) answers the same questions, with the measured edges. - Describe people by role, not by name, unless the name is written on screen: a model guessing who someone is can be wrong, and a wrong name in a caption is worse than none.
- Price follows length. A video is mostly input: Gemini 3 models read about 90 tokens per second of video, sound included. The six-minute briefing of the lab was 34,042 tokens read and cost 1.88 credits with Gemini 3.8 Flash, about 0.31 credits per minute (Gemini 2.5 Flash reads three times as many tokens per second: 2.34 credits for the same video). The estimate before the run does not yet count the length of the video, so it shows much less: budget by the minute. To read only part of a long video, cut it first with Trim Video.
- Gemini 3.8 Flash reasons before it answers (799 tokens in the lab, at its default Reasoning Effort
medium): leave Max Tokens at its default, which is 4096.lowthinks less;highthinks more and costs more. The other Gemini models can be chosen on the node: 3.5 Flash-Lite is cheaper and found only four chapters in the lab, 3.1 Pro costs about three times as much.
Document Analysis
Section titled “Document Analysis”The node sends PDFs to the model as files — text, tables, layout and pictures together — and reads text and Markdown files itself, passing their content as text. Several documents can be read in one question: compare these two quotes, does this contract match this order.
- Copy, do not compute. Ask the model to copy figures as printed and never to compute, round or correct them; then
check the arithmetic with Calculate. A model reads a table well and adds it up less well,
and the check costs nothing. In the lab the sum of the lines and the total are recomputed from the model’s own
reading: a gap of
0means the quote was read as printed. - Dates in ISO form. Ask for
YYYY-MM-DD, so that Format as Text and a comparison can read them. - Absence is an answer. Ask the model to leave a key out when the document does not have it — no payment terms, no deposit — and read it with When Missing in Extract.
- Limits. Up to 20 documents per step. The total size per request is 50 MB with GPT models and 32 MB with Claude;
a larger set is refused before any charge with
DOCUMENT_LIMIT_EXCEEDED. With Claude models — and for text and Markdown files with any model — the step also counts the document’s tokens before sending and refuses what would not fit the model’s context, naming what to change.
Try it: a supplier’s quote and a press briefing
Section titled “Try it: a supplier’s quote and a press briefing”The lab has two independent parts. A joinery’s quote for a kitchen renovation — a one-page PDF — is read into data and checked; a six-minute NASA press briefing on the Artemis programme is indexed into a summary and chapters.
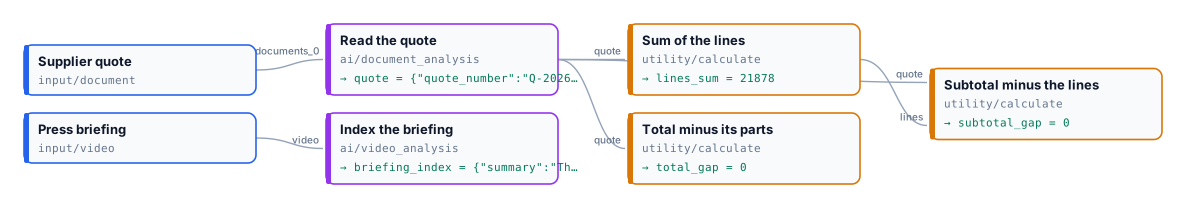
The quote. The model read every line, the subtotal, a discount of €1,000, VAT at 13.5% and the total:
{ "quote_number": "Q-2026-0417", "supplier": "Brightwork Joinery", "valid_until": "2026-11-01", "lines": [ { "description": "Shaker kitchen units in painted ash: 9 base and 6 wall units, soft-close hinges and drawers", "quantity": 1, "unit": "set", "unit_price": 11850.00, "amount": 11850.00 }, { "description": "Quartz worktop, 30 mm, with undermount sink cut-out and upstand", "quantity": 6.4, "unit": "m", "unit_price": 420.00, "amount": 2688.00 }, "… four more lines …" ], "subtotal": 21878.00, "discount": 1000.00, "vat_rate": 0.135, "vat": 2818.53, "total": 23696.53, "deposit": 7000.00}| Check | Expression | Result |
|---|---|---|
| Sum of the lines | sum(quote.lines[*].amount) |
21878 |
| Subtotal minus the lines | round(quote.subtotal - lines, 2) |
0 |
| Total minus its parts | round(quote.total - (quote.subtotal - quote.discount + quote.vat), 2) |
0 |
The quote has no payment terms, and the model left the key out, as asked. Reading it cost 0.046 credits with GPT-6 Luna.
The briefing. Four speakers (correct), a three-sentence summary and eleven chapters:
{ "chapters": [ { "start": "0:00", "title": "Origins and goals of the Artemis program" }, { "start": "0:57", "title": "Reusable architecture and the Gateway" }, { "start": "2:29", "title": "The Moon as a proving ground" }, { "start": "2:59", "title": "Reid Wiseman on nationwide industry involvement" }, "… seven more …" ], "speakers": 4}Compared with the captions of the same briefing, the chapters start on the phrase they name or up to three seconds before it — proving ground at 2:29, said at 2:29; the second speaker at 2:59, who begins at 3:00. Gemini 3.8 Flash read 34,042 tokens and reasoned for 799; indexing it cost 1.88 credits.
The whole run costs about 1.9 credits, almost all of it the video.
node madoo-install-example.mjs lab-video-and-documents --api <your Madoo API URL> --key <key.json> --runMedia: the quote is a fictional document made with the F12 quote template; “Artemis Media Resource — Interview Soundbites”, NASA (public domain; NASA does not endorse this documentation).
When something goes wrong
Section titled “When something goes wrong”| Code or symptom | Node | What happened | What to do |
|---|---|---|---|
DOCUMENT_LIMIT_EXCEEDED |
Document Analysis | the documents are larger than the provider accepts in one request | split them across steps, or compress the PDFs |
TOO_MANY_DOCUMENTS |
Document Analysis | more than 20 documents | split them across steps |
| a refusal before the call, naming the model’s limit | Document Analysis | the documents do not fit the model’s context | fewer pages per step, or a model with a larger context |
MISSING_PROMPT |
both | no question | write the prompt, or connect it |
AI_RESPONSE_INCOMPLETE |
both | the model reached Max Tokens | raise Max Tokens |
| a figure that does not add up | Document Analysis | the model misread or computed | ask it to copy as printed; recompute with Calculate and compare |
| a time a few seconds off | Video Analysis | times from a video model are approximate | use Speech to Text captions for exact times |
| the run cost far more than estimated | Video Analysis | the estimate does not count the video’s length yet | budget about 0.31 credits per minute with Gemini 3.8 Flash; trim the video first |