

Transcription and captions
Most video on social networks is watched with the sound off, so a clip that relies on what is said must also show it. Captions also make a video accessible to people who cannot hear it, and a caption file makes what is said searchable. In Madoo the work is split in two steps: Speech to Text turns the speech into text with timing — this is the only paid step — and Video Subtitles turns that timed text into captions, drawn on the picture or written to a caption file, locally and at no credit cost. This page explains both steps, what a caption file is, how captions are made to look right, and ends with two labs.
From speech to timed text
Section titled “From speech to timed text”Speech to Text (ai/speech_to_text) takes audio. To transcribe a video, first take its sound with Extract
Audio (video/extract_audio) and the speech profile, which keeps a compact mono track that is all a
transcription model needs. The node always returns the whole transcript as plain text on text; what else it
returns depends on Timing Detail (granularity):
text— only the text, no timing. Enough for a summary, a translation or a search index; not enough for captions.segment— the text cut into phrases, each with its start and end time.word— every word with its own start and end time. Captions need it to highlight the word being spoken, and it also makes better phrases: they can be cut exactly where a word ends.
With segment or word, the timing arrives on segments as a madoo.transcript-segments/v1 document — the same
shape whatever model produced it — and Caption Sidecars (caption_format) can add an SRT file on srt, a
WebVTT file on vtt, or both. Leave Language empty to let the model detect it, or set it (en, it, de…)
when you know it: a short clip gives a model little to detect a language from. Identify Speakers
(diarization) labels who is speaking, for interviews and conversations. Task translate transcribes and
translates into English in one pass; for any other target language, transcribe and then translate the captions
with Caption Translation.
Choosing the model
Section titled “Choosing the model”| Model | Word timing | Speakers | Translate to English | Cost | What to expect |
|---|---|---|---|---|---|
| ElevenLabs Scribe V2 (the default) | yes | yes | no | 0.5 credits per started minute of audio | real pauses between words; transcribes verbatim, repetitions and “uh” included |
| Whisper | yes | yes | yes | 0.05 credits per second of processing | a clean text without fillers; word timings touch each other, with no pause between words |
| Wizper | no | no | yes | 0.07 credits per second of processing | a fast Whisper for segment timing only |
On a 25-second interview Scribe cost 0.5 credits and Whisper 0.37. Scribe’s pauses make captions appear and
disappear with the voice; Whisper’s cleaner text reads better when the speaker hesitates a lot. A combination the
chosen model cannot do — word timing from Wizper, translation from Scribe — is refused when the workflow is
validated, before anything is paid (UNSUPPORTED_MODEL_CAPABILITY), and so is a caption file requested with
granularity: text (TIMING_REQUIRED).
Speech to Text writes down what was said, not what should have been said. In the labs below the astronaut says “this, this program” and the captions say so too. When the words must be tidied — a hesitation removed, a name spelled the brand’s way — edit the text before the captions are drawn, or pass it through a language model that is told to change nothing but that.
Caption files: SRT and WebVTT
Section titled “Caption files: SRT and WebVTT”Captions reach a viewer in one of two ways. Burned in (also called open captions), the text is drawn into the pixels of the video: it is always there, in the look you chose, on every platform — which is why social clips are captioned this way — but it cannot be turned off, restyled or swapped for another language. In a caption file (closed captions, or a sidecar, because it travels beside the video), the text stays separate: the player draws it, the viewer can switch it on or off and choose a language, and a search engine can read it. YouTube, LinkedIn, Vimeo, a course platform or a web page with a video player take such a file next to the video.
A caption file is a plain text file: a list of cues, each with the moment it appears, the moment it disappears and the text to show. The two formats you will meet are almost the same:
300:00:03,300 --> 00:00:04,280doing this, thisprogram,
400:00:04,340 --> 00:00:05,019the Artemis program.
SRT (SubRip, .srt) is the one above — two cues from the first lab: a number, the times with a comma before
the milliseconds, one or two lines of text, an empty line. It is the most widely accepted format — video editors,
YouTube, Facebook, LinkedIn.
WEBVTT
00:00:00.140 --> 00:00:01.560This is not NASA doing this.
00:00:01.700 --> 00:00:04.000This is the United States of America doingthis, this
WebVTT (.vtt) is the web’s format: it starts with the word WEBVTT, has no numbers, uses a dot before the
milliseconds and can carry the language of the captions. A web page’s video player reads it with a <track>
element; so do most course and streaming platforms.
Madoo writes both from two places. Speech to Text gives them straight from the transcript, grouped into phrases —
the quick route when you need only the file. Video Subtitles gives the file laid out exactly as the burned-in
captions — the same phrases, cut at the same points — with mode: both, or only the file, without touching the
video, with mode: sidecar. Video Subtitles also reads an SRT or WebVTT you already have on its SRT or WebVTT
input, instead of a transcript, to burn it in or to convert it.
Captions on the video
Section titled “Captions on the video”Video Subtitles (video/subtitles) takes the video and either the transcript’s segments or an existing
caption file on captions — one of the two, never both (CAPTION_INPUT_XOR). Output Mode (mode) chooses
burn_in (the captioned video), sidecar (only the caption file, in sidecar_format SRT or VTT; the video is not
re-encoded) or both, the default.
Caption Presentation (presentation) decides what the viewer sees:
block— whole phrases of one or two lines, the way subtitles look on television. It works with any timing, and it is the right choice for anything longer than a minute, for interviews and for training videos.one-word— one word at a time, large, in the middle of the frame: the rhythm of a fast social clip.highlight-word— the phrase stays on screen and the word being spoken changes colour (Current Word Color,highlight_color): the style of most reels today, readable and lively at once.
The two word presentations need word timing. With segment timing they stop before the video is read
(WORD_TIMING_REQUIRED); a caption file made from them still holds readable phrases.
Lines per Caption (max_lines, 1 to 3) and Characters per Line (max_characters_per_line) decide how a
phrase is cut. For a phrase that would not fit, Video Subtitles cuts it where a word ends, and on word timing each
part keeps the real time of its words. For highlighted words on a phone screen, a short line — 14 to 18 characters —
gives the two to four large words at a time that social clips show. Cue Transition (cue_transition) fades
each caption in and out. Speaker Labels (speaker_labels) shows who is speaking when the transcript knows it:
auto shows labels only when they can be trusted across the whole video, hide is right for a single speaker.
Overlapping Captions (overlap_policy) settles two captions that would be on screen at once: the earlier one
is cut short (trim_previous, the default), both are kept (preserve) or the step fails (fail).
Typography: how captions look
Section titled “Typography: how captions look”What makes a caption look professional — the font, its size, where it sits, how it stands out from the picture —
is described by the Caption Style (typography), a madoo.video-typography/v1 object. It is the same object
that styles text on video with Text on Video (video/text_overlay), so a brand’s captions and titles can share
one style. In the editor it is a panel with presets; through the API you send the object. Its parts:
- Font — an exact font from the workspace’s library: the system fonts (Roboto, Montserrat, Inter, Poppins,
Oswald, Bebas Neue and others) or a font the workspace uploaded, such as a brand typeface. The reference names a
version and its fingerprint, so a workflow draws the same letters next year as today. If the font lacks a
character of the text — Cyrillic, Greek, Arabic in a Latin-only font — the step stops and names the character
(
FONT_GLYPH_COVERAGE_INSUFFICIENT) instead of drawing empty boxes. - Size —
fixedin pixels, orrelative: a percentage of the video’s height, so the same style reads the same on a 720p and a 4K video.minandmaxbound it. The size is the size of the letters, as in a design tool or a web page — the editor’s preview shows it as the video will — so the same value gives the same size in any font. - Text — colour, opacity,
uppercaseorlowercase, the spacing between letters and between lines. - Layout — where the text sits: one of nine anchors (
top-left…center…bottom-right), moved by an offset in percent of the frame; the widest a line may be (maxWidthPercent); and what to do when the text does not fit:fitmakes it smaller down tomin,clipdrops the lines beyond the limit,failstops (TEXT_OVERFLOW). - Safe area — the margins the text never enters.
title-safekeeps it clear of the edges of a screen;social-portraitkeeps it clear of what a vertical feed draws over the video — the name, the description and the buttons at the bottom and on the right;customsets each margin. - Outline, shadow, background — what separates the letters from a busy picture: a dark outline, a soft shadow, or a translucent box behind the text.
- Motion — a fade in and out, over a set number of milliseconds.
A word presentation with no Caption Style uses the catalog’s: Roboto, sized relative to the video, on a translucent
box, inside the social-portrait safe area — the style the editor fills in. A block caption with no Caption Style
is drawn by a simpler renderer driven by the older parameters (font_family, font_size, position, background
and the others); pass a Caption Style whenever the look matters. Typography on video goes
further: fonts of your own, titles, lower thirds and several text layers at once.
Lab 1: captions on a vertical reel
Section titled “Lab 1: captions on a vertical reel”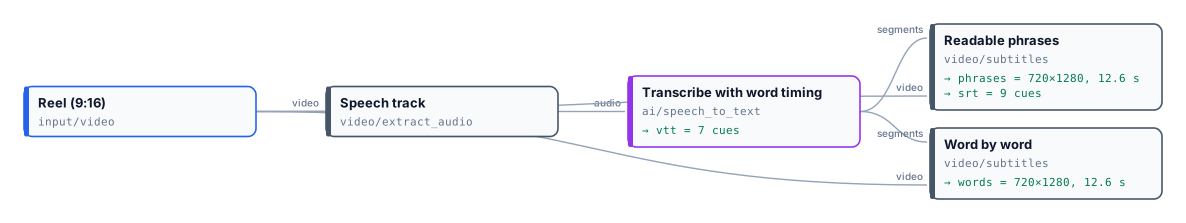
The vertical reel made in the editing lab is transcribed once, with word timing, and captioned twice from the same timing. Readable phrases shows whole phrases in Roboto on a translucent box, inside the social safe area, and writes the same phrases to an SRT file. Word by word shows two to four words at a time in bold capitals with an outline and a shadow, the spoken word in yellow, 16 characters per line. The WebVTT file comes straight from Speech to Text.
| Readable phrases | Word by word | |
|---|---|---|
| Watch | ||
| On screen | 9 phrases of one or two lines, in a box | two to four words in capitals, the spoken one in yellow |
| Caption file | SRT, 9 cues, cut like the picture | WebVTT from Speech to Text, 7 cues, two lines of 42 characters |
| Credits | 0.5 for the transcription, shared | captions: 0 |
Both reels are 720×1280 and 12.6 s, re-encoded at 540×960 for this page.
The SRT has shorter lines than the WebVTT, and that is on purpose. At 4.3% of the height — the default size — a line of 42 characters does not fit the width of a 720-pixel frame, so Video Subtitles halved the line to 21 characters and cut again — both the picture and its caption file, which therefore match. Speech to Text does not know the frame, and writes its file in the usual two lines of 42 characters. Every phrase in both files keeps the real time of its words — “the Artemis program.” starts at 4.34 s, the instant “the” is spoken — and no sentence is closed by a word left alone on screen: when the end of a sentence would last less than a second, it takes the last words of the phrase before it, and the break falls after a comma or a full word, never after “of” or “the”.
node madoo-install-example.mjs lab-captions --api <your Madoo API URL> --key <key.json> --run --save captionsLab 2: a landscape video in a vertical feed
Section titled “Lab 2: a landscape video in a vertical feed”A landscape video cropped to 9:16 loses two thirds of its picture — often what mattered. The other way, common on social networks, keeps the whole picture: the video sits across the middle of a vertical frame, with a black band above and below, and the bands carry the text — a title above, the captions below — so no word ever covers a face.
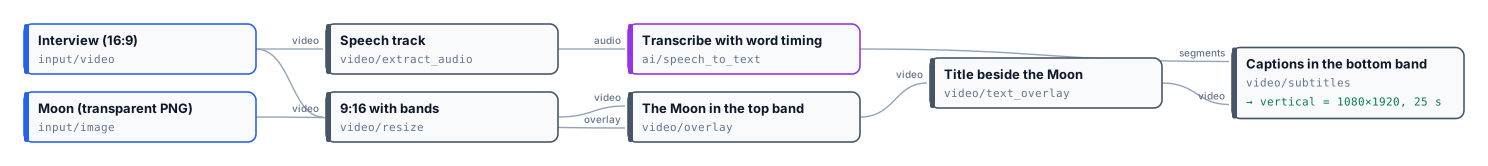
Resize Video (video/resize) with fit_mode: letterbox puts the 1280×720 interview into a 1080×1920 frame:
the picture fills 1080×608 across the middle and leaves two black bands of 656 pixels. The top band then gets a
picture and a title, the bottom band the captions:
- Video Overlay (
video/overlay) lays a picture of the Moon over the video. It is a PNG with a transparent background, so only the disc shows;position: top-rightwith amarginof 180 pixels and ascaleof 28% of the width (302 pixels) puts it at the right of the band, its middle on the band’s middle. Any graphic can go on a video the same way: a logo, a sticker, a product cut out of its background, a frame around the picture. - Text on Video writes the title as three layers of one text track, each with its own style, left-aligned beside the Moon: the speaker’s name in small grey capitals, “We’re going back to” in Montserrat ExtraBold, and “the Moon” twice as large in Montserrat Black, in yellow. Splitting a title into layers is how one word gets its own size or colour.
- Video Subtitles puts the captions in the bottom band: anchor
center, moved down by 32.9% of the frame’s height, which is the middle of the lower band ((1920 − 1264) ÷ 2 + 1264 = 1592 pixels from the top, 632 below the centre).
Each position is a percentage of the frame, worked out once: a layout that sits in the bands is a matter of offsets, not of guesswork, and it holds for every video of the same shape.
The vertical video, re-encoded at 540×960 for this page; the run’s own output is 1080×1920, 25 s.
| Step | Result |
|---|---|
| Frame | 1080×1920; the whole 16:9 picture at 1080×608, between y 656 and 1264 |
| Top band | the Moon on the right; on the left the name, “We’re going back to” and “the Moon” in yellow |
| Bottom band | captions centred at 1592 px, the spoken word in yellow; nothing drawn over the picture |
| Credits | 0.5, the transcription; framing, the picture, the title and the captions cost nothing |
node madoo-install-example.mjs lab-letterbox --api <your Madoo API URL> --key <key.json> --run --save letterboxMedia: “Artemis Media Resource — Interview Soundbites”, NASA (public domain; NASA does not endorse this documentation). The Moon in Lab 2: “Full Moon”, NASA’s Scientific Visualization Studio from Lunar Reconnaissance Orbiter data (public domain), cut out of its black background for this lab. Music in the reel of Lab 1: “Local Forecast – Elevator” Kevin MacLeod (incompetech.com), licensed under Creative Commons: By Attribution 4.0 License, http://creativecommons.org/licenses/by/4.0/.
Long recordings and other languages
Section titled “Long recordings and other languages”Speech to Text sends the audio to the provider as a job and waits for it without holding a worker, so a recording
of several minutes is transcribed in one step. For a recording too long for one pass — a lecture, a podcast
episode — the audio is cut into segments, each is transcribed, and Aggregate Transcript
(aggregate/transcript) joins the timings back into one transcript on the timeline of the whole recording; the
page on long media in this section explains it. To caption in another language, Caption Translation
(ai/caption_translation) translates the timed captions while keeping their timing, and Selectable Caption
Tracks (video/caption_tracks) offers several languages beside the untouched video, one WebVTT file each, for the
viewer to choose from — Translating captions explains both.
When a step fails
Section titled “When a step fails”| Code | Meaning | Fix |
|---|---|---|
UNSUPPORTED_MODEL_CAPABILITY |
the chosen model cannot do what was asked — word timing from Wizper, speakers from Wizper, translation from Scribe | choose Scribe V2 or Whisper, as in the table above |
TIMING_REQUIRED |
a caption file was asked of Speech to Text with granularity: text |
set granularity to segment or word |
PROVIDER_TIMING_MISSING |
the model returned the text but no timing; the text is kept and paid | run again, or choose another model |
PROVIDER_SPEAKERS_MISSING |
speakers were asked for, the model found none | turn Identify Speakers off for a single speaker |
CAPTION_INPUT_XOR |
Video Subtitles received both a transcript and a caption file | connect one of the two |
WORD_TIMING_REQUIRED |
a word presentation received segment timing | transcribe with granularity: word, or use block |
INVALID_SRT, INVALID_VTT, EMPTY_CAPTIONS |
the caption file on the input could not be read, or holds no cue | check the file: times, the empty line between cues, WEBVTT at the top of a WebVTT |
OVERLAPPING_CAPTIONS |
two captions overlap and overlap_policy is fail |
fix the file, or choose trim_previous |
TYPOGRAPHY_INVALID |
the Caption Style is incomplete or out of range — a missing font, an unknown anchor, margins that leave no room | the message names the field; start from a preset in the editor |
FONT_GLYPH_COVERAGE_INSUFFICIENT |
the font has no letter for a character of the text | choose a font that covers the language |
TEXT_OVERFLOW |
a caption does not fit its safe area and overflow is fail |
allow more lines, a wider line, a smaller minimum size, or overflow: fit |
VIDEO_TOO_LARGE, MEDIA_WORK_CAPACITY |
the video is larger than the step accepts, or the worker is busy with other media | cut long videos into segments; a busy worker is retried automatically |