

Spreadsheets and datasets
Much of the data a workflow works on arrives as a table: a price list exported from the management system, a product feed, the attendees of a course, the lines of an order. Madoo reads a table in two steps, each a node that costs nothing:
- Data Input (
input/data) reads the file — Excel (.xlsx), CSV or a JSON array — and turns it into a dataset: the rows, the columns and a profile, whatever the format was. It does not multiply anything. - Data Rows (
enumerate/data_rows) gives one iteration per row, with the columns you choose as typed outputs. Every node after it runs once per row, in parallel — see Iteration.
Keeping the two apart is what lets the same workflow read an Excel file today and a CSV tomorrow, and what lets Madoo count the rows — and so the credits — before anything runs.
Look at the file first
Section titled “Look at the file first”Before configuring the nodes, inspect the file: POST /api/v1/structured-data/inspect on REST,
inspect_data_source on MCP and in the AI Assistant. Inspection reads the uploaded file without running anything and
returns the exact row count, the columns with their probable types, a few sample rows and any warnings. It is the
moment to catch a wrong separator or a wrong language, when fixing it costs nothing.
Configure Data Input with the same options:
| Option | Meaning |
|---|---|
format |
auto, csv, json or xlsx |
table |
the worksheet of an Excel file (optional when only one is visible), or the array of a JSON document ($.products) |
headerRow |
the row with the column names; 1 by default |
locale |
the language the numbers of a CSV are written in: it-IT, de-DE, en-US… (invariant by default) |
delimiter |
the CSV separator; detected when omitted |
formulaPolicy |
Excel formulas: cached_value reads the value Excel saved, reject refuses a file with formulas |
emptyBehavior |
fail (default) or allow_empty for a table with no rows |
maxRows |
the largest table accepted |
The file saved in the node is a default. At run time the node’s input — named after the node, like any other input — takes the file of the day as an uploaded asset, and the parsing options stay the same.
How cells become values
Section titled “How cells become values”Values are typed and never guessed. For a table that means:
- Numbers in a CSV follow
locale, and a number is read only when it is unambiguous. Withit-IT,19,90and1.234,50are numbers; with the defaultinvariant, only19.90is. A value that does not fit the locale stays text — never a silently different number:19,90without a locale is the text"19,90", not 1990. The profile then carriesCSV_AMBIGUOUS_NUMBER, naming the column. - Excel cells keep the type Excel gave them. A number is a number and a date is a date, whatever the display
format;
localedoes not apply. Formulas are never executed. - Codes stay codes. A value with a leading zero (
00501) is text. A code made only of digits, such as an ISBN or an EAN, may be read as a number; map it to atextoutput and its digits pass unchanged. trueandfalseare booleans in any letter case. Rows whose every cell is empty are not rows.- A CSV that is not UTF-8 is read as Windows-1252 (what Excel saves as “CSV” in Western Europe), with a warning, so
àand€survive.
One iteration per row
Section titled “One iteration per row”Data Rows maps the columns you need to outputs. Each entry of rowMapping.columns names the sourceColumn exactly
as in the file, the outputPort the graph connects to, and an outputType: text, number, boolean, json,
url, any, or a file type — image, video, audio, document (see Files in a column). Conversion is strict: a cell that cannot be the declared type stops the node with
ROW_CONVERSION_FAILED, instead of passing a wrong value to every step after it. The check is on the whole
file, not per row: one bad cell fails the node before any iteration starts, the steps after it are cancelled and
the run ends partial_success. To keep the good rows and set the bad ones aside, pass each row as JSON to a
validation step instead (see D05). An empty cell is null on a
number, boolean, URL or file output, and an empty text on a text output: a Text Template fills its marker with nothing and
the step goes on, so an optional column (notes, a second address line) needs no special handling.
Every row also has row (all its values as one JSON object), row_index (its position in the file) and row_id
(a stable identity, the same in every run of the same file), for workflows that must trace a result back to its
row. startRow and maxRows process a slice of a long table.
To bring the rows back together, end the branch with an aggregator: Generate JSON (aggregate/json) for a
structured list, Generate CSV (aggregate/csv) for a file to download, or a document or media aggregator. To
leave some rows out, put a Filter on one of the collected values and set that column’s
whenAbsent to skip_row (Generate JSON and Generate CSV both have it): a rejected row is dropped from the list
instead of becoming a row of empty cells.
Files in a column
Section titled “Files in a column”A table often names a file per row: the photo of a product, the clip of a hotel, the recording of a guide, the PDF of
a quote. Declare that column as image, video, audio or document, and its port carries the file of each
row — ready for a template’s image field, an AI step or a merge — instead of its name as text. A cell holds either:
- the asset path of a file uploaded to the workspace, as an upload returns it
(
…/assets/5e58…/manarola.jpg): the file stays private; - or an HTTP(S) URL: Madoo downloads the file, with the same limits as every other download (size, type, no internal addresses), and keeps a copy for the run.
| sku | name | photo |
|---|---|---|
| NC-01 | Linen throw | 388232e9…/3uOe…/assets/5e58…/throw.jpg |
| NC-02 | Stoneware mugs | https://cdn.example.com/mugs.jpg |
Each file is checked when the row’s value is stored: a path must name a file of this workspace (a table cannot
reach another customer’s files), the file must exist and be of the column’s kind (a PDF in an image column is
refused). A refused file fails the node and the message names the column and the row — Output 'photo', item 3: the referenced asset does not belong to this workspace — so the table can be fixed. An empty cell is no file: the
port carries nothing for that row, and an optional template field stays empty.
Before file columns, the way to a photo per row was a public URL in the table and Media from URL after the enumerator: two steps, and photos anyone with the link could open. A file column does it in one, with private files.
The lab
Section titled “The lab”The spreadsheets lab reads the price list of a small
publisher of classics — six books, with ISBN, title, format, price and stock — and makes a catalog of the books in
stock with their price including Italian VAT on books (4%). The same list exists twice, as an Excel workbook and as
a CSV saved in Italian (semicolons, 12,50).
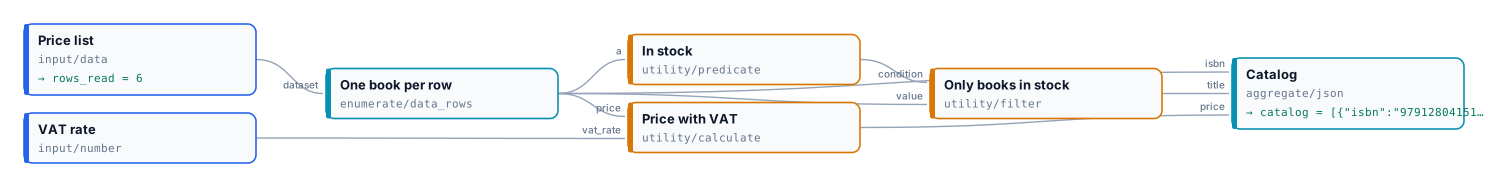
Data Input reads the file with locale: it-IT. Data Rows maps ISBN and Titolo as text, Prezzo and
Giacenza as numbers, and leaves Formato out. For each book, Calculate computes
round(price * (1 + vat_rate), 2), a Predicate checks the stock, and a Filter passes the title only when the book
is in stock. Generate JSON collects ISBN, title and price, and drops the rows whose title was rejected.
| Book | Price | Stock | In the catalog |
|---|---|---|---|
| The Odyssey | 12,50 | 40 | 13.00 |
| Pride and Prejudice | 9,90 | 25 | 10.30 |
| Moby-Dick | 24,00 | 0 | — out of stock |
| I promessi sposi | 28,50 | 12 | 29.64 |
| Frankenstein | 10,90 | 8 | 11.34 |
| Il Principe | 6,50 | 60 | 6.76 |
Both files give the same result: 6 rows read, 5 books in the catalog, ISBNs intact as text, no credits. Read the CSV
with the default invariant locale instead, and inspection warns CSV_AMBIGUOUS_NUMBER on Prezzo; run it anyway,
and Data Rows stops with ROW_CONVERSION_FAILED, because 12,50 is text and the column was declared a number. The
catalog is missing — and no price was ever read as 1250.
node madoo-install-example.mjs lab-spreadsheet --api <your Madoo API URL> --key <key.json> --runThe installer uploads both files and runs the Excel one; the CSV run is in
run-inputs-csv.json.
Credits before the run
Section titled “Credits before the run”Because Data Input counts the rows exactly, an estimate made with the same file knows how many times each step after Data Rows will run, and reserves exactly that. Estimate with the file you will run, not with the sample saved in the node: an estimate without the file can only report the part it knows, and is never free.
Data Input or CSV Input
Section titled “Data Input or CSV Input”CSV Input (input/csv) holds a small table inside the workflow and fans out directly. It can read separators
column by column and add computed columns. Use it for a fixed list that belongs to the workflow — the five sizes of
a banner, the languages of a campaign.
Use Data Input and Data Rows for a file that changes from run to run, for Excel and JSON as well as CSV, and
whenever the row count must be known before running. CSV Enumerator (enumerate/csv) is for a CSV produced
inside the workflow, for example by an AI step.
Errors
Section titled “Errors”| Code | Cause | Fix |
|---|---|---|
UNSUPPORTED_FORMAT |
the file is not CSV, JSON or XLSX (.xls and .xlsm are refused) |
save it as .xlsx or CSV |
AMBIGUOUS_TABLE |
the workbook has several visible sheets, or the JSON several arrays | set table |
TABLE_NOT_FOUND |
table names a sheet or an array that does not exist |
use a name from the inspection |
DUPLICATE_COLUMN |
two columns have the same name (letter case ignored) | rename one |
EMPTY_DATA |
the table has no rows and emptyBehavior is fail |
check the file, or allow an empty table |
ROW_LIMIT_EXCEEDED |
more rows than maxRows |
raise the limit or split the file |
DATASET_COLUMN_NOT_FOUND |
a sourceColumn is not in the file |
copy the name from the inspection |
ROW_CONVERSION_FAILED |
a cell cannot be the declared type — often a number in the wrong locale | set locale, or declare the column as text |
MEDIA_SOURCE_INVALID |
a file column names a file of another workspace, a file that does not exist, or one of another kind (the message gives the output and the row) | upload the file to this workspace and put its asset_path in the cell, or give a public URL |