

X04 — Documents sorted, then read the right way
The documents that reach a back office do not come sorted. An invoice must give its supplier, number, total and due date; a quote its validity; a contract its parties, term and notice. Reading every document with every extraction costs three times what it should and fills the records with nonsense. This workflow asks Decide with a Model what each document is, and lets only the matching extraction run.
Two reference runs: an Italian invoice and an English contract, each sorted and read once — 0.013 credits each. Invoice outputs · contract outputs.
The case
Section titled “The case”The back office of a small design agency. A printer’s invoice, in Italian: “FATTURA N. 2026/0412 — Data: 3 ottobre 2026. Fornitore: Tipografia Lario Srl … Totale da pagare 463,60 EUR. Pagamento con bonifico entro il 2 novembre 2026.” A service agreement, in English: “SERVICE AGREEMENT between Alpha Media Ltd (the Provider) and Bianchi Design (the Client). 1. Term: twelve months from 1 November 2026 … either party may terminate with 60 days’ written notice …” The documents are the example’s own.
What it shows
Section titled “What it shows”- Sort first, read once. What kind of document is this? — invoice, quote, contract or other, each with a description — then a Predicate and a Filter per kind in front of its extraction. The two extractions that do not fit are skipped, and cost nothing.
- Sure, and in either language. Both documents were sorted with probability 1.00; on our 32-document measurement set every kind was right in English and Italian.
- A second question for free, almost. “The document states an amount of money to pay or to be paid”:
truefor the invoice,falsefor the contract (its fees are in a schedule it does not include) — the same call, a few more tokens. - The extraction is a writing step. Text Generation in JSON mode with a prompt per kind, told to use only what the document says. For a PDF, use Document Analysis on the same branches.
The workflow
Section titled “The workflow”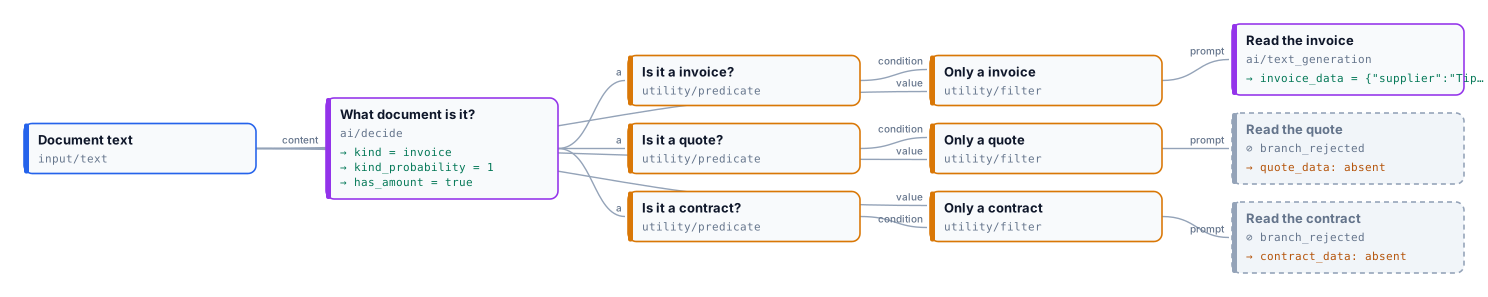
| Node | Type | Why |
|---|---|---|
| Document text | input/text |
The text of the document |
| What document is it? | ai/decide |
kind (invoice, quote, contract, other, at 0.7) and has_amount |
| Is it an invoice / a quote / a contract? | utility/predicate equals |
One condition per kind |
| Only an invoice / a quote / a contract | utility/filter |
The text passes only into its branch |
| Read the invoice / the quote / the contract | ai/text_generation, json_object |
The fields of that kind |
Reading a run
Section titled “Reading a run”| The invoice (Italian) | The contract (English) | |
|---|---|---|
| Kind | invoice, 1.00 |
contract, 1.00 |
| States an amount | true |
false |
| Read | {"supplier": "Tipografia Lario Srl", "customer": "Studio Verdi Srl", "number": "2026/0412", "date": "2026-10-03", "total": 463.6, "currency": "EUR", "due_date": "2026-11-02"} |
{"kind": "Service Agreement", "parties": ["Alpha Media Ltd", "Bianchi Design"], "term": "Twelve months from 1 November 2026", "notice": "Either party may terminate with 60 days' written notice.", "governing_law": "The laws of Italy"} |
| Skipped | the quote and contract readings | the invoice and quote readings |
Cost: 0.013 credits a document — 0.003 to sort it, 0.01 for the one reading. Reading each document three ways would cost 0.03 and give two wrong records.
Install it
Section titled “Install it”node madoo-install-example.mjs x04-document-intake --api <your Madoo API URL> --key <key.json> --runThe contract’s inputs are in run-inputs-contract.json.
Change it
Section titled “Change it”- Your kinds: purchase orders, delivery notes, CVs, claims — an option each, and a branch for the kinds that need a reading; other filed with a note.
- Your fields: the prompt of each reading, checked with Validate JSON Schema before it is recorded.
- Many documents: an iteration over the batch, and a JSON Aggregator for the records.
- A person for the rest: a Filter on
all_acceptedinverted sends the documents the model was not sure about to a review list.